
The question
How can several specialist agents work over the same documents while keeping model inference on local infrastructure?
The approach
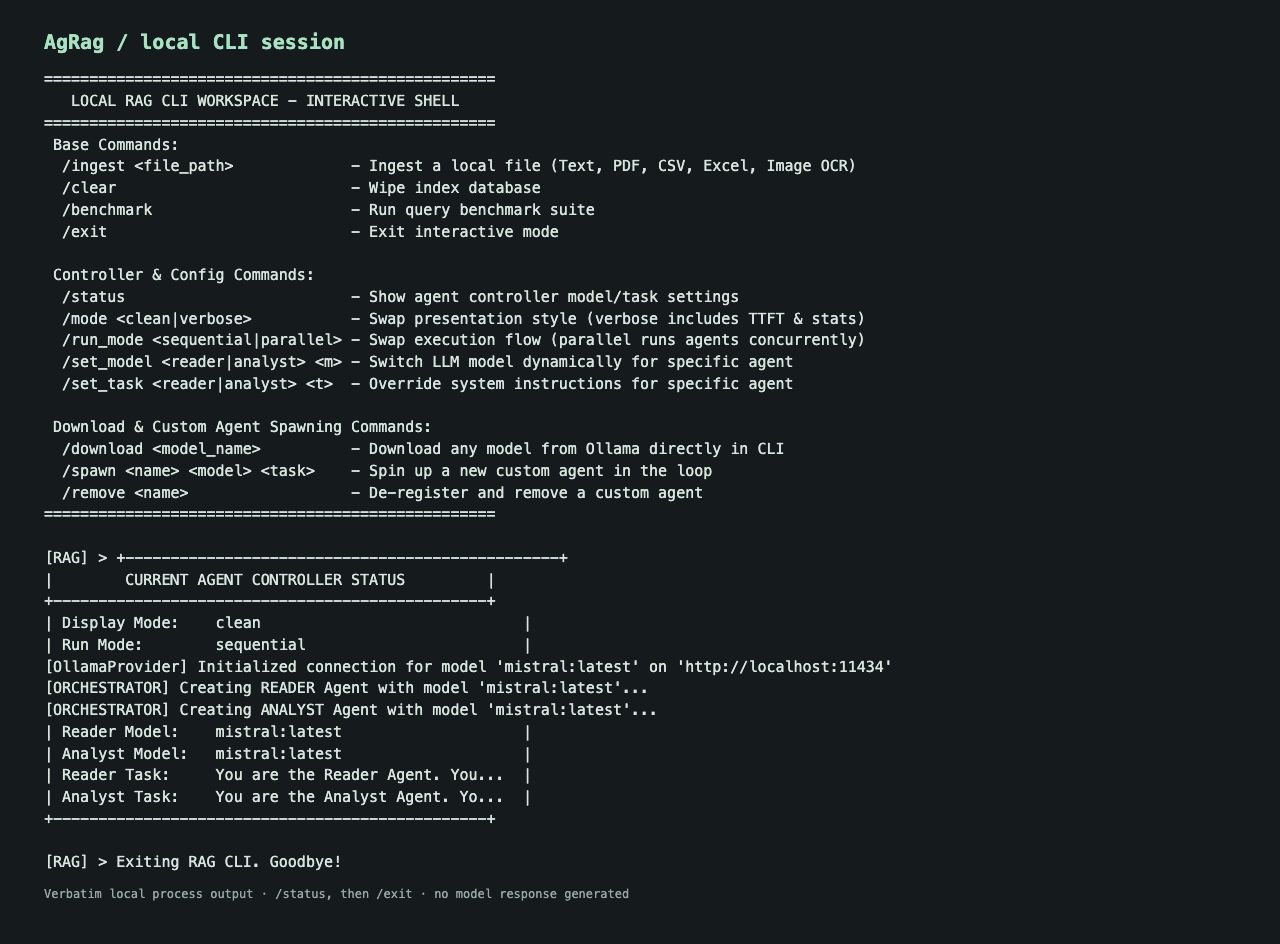
A Python CLI connects document parsers, a NumPy similarity store, and Ollama. Reader and analyst agents share context; commands configure models, spawn additional agents, and compare sequential and parallel execution. The implementation builds on llama-cpp-agent components.
The result
An implemented local retrieval and orchestration project. Its strongest story is the control over ingestion, context, and agent execution; hardware performance depends on the models and machine used.
Project summary shared with permission. Source code is private; contact me to discuss the work.