
The question
Scanned documents mix layouts, handwriting, dates, and financial values. Downstream software needs structured fields rather than another unsearchable PDF.
The approach
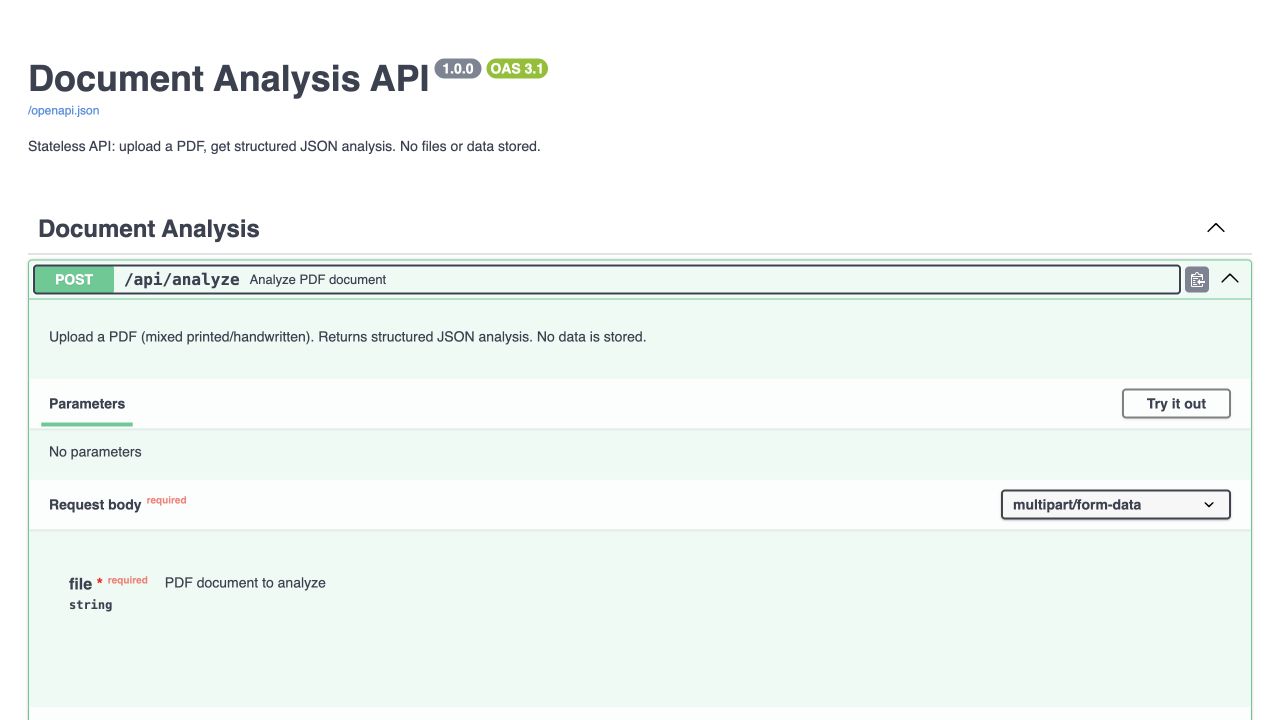
The FastAPI vision-analysis variant accepts PDFs, prepares pages, calls a configured model provider, and validates a structured response. The repository also explores Azure OCR/classification and offline extraction variants; those paths have different setup and processing requirements.
The result
An implemented document-processing project with upload validation and a documented API contract. The current API variant is designed to process without retaining submitted documents; extraction accuracy still needs evaluation on representative material.
Project summary shared with permission. Source code is private; contact me to discuss the work.